Audio
Open ASR transcribes. EdgeLance attributes.
Open-source acoustic models do the transcription. EdgeLance adds the speaker, the doctrine, the citation, and the replay.
In the product
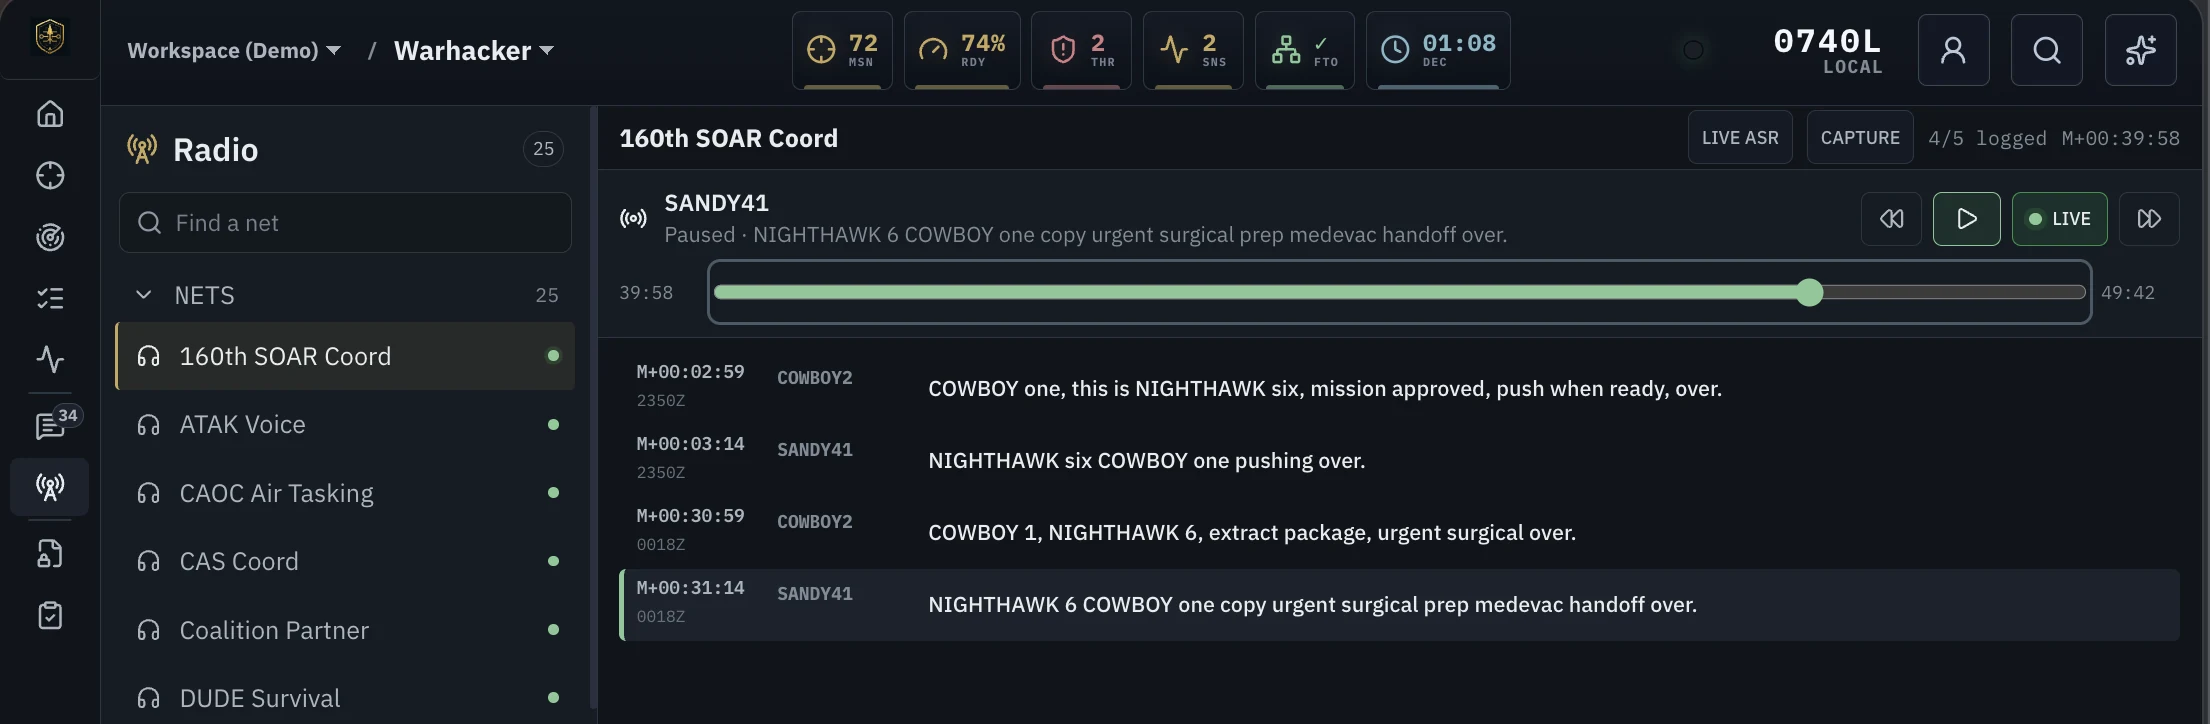
Every word stays tied to speaker and time.
Live radio traffic becomes attributed, timestamped, replayable mission context. Operators can capture a net, review exact phrases, and preserve the source instead of relying on a detached transcript.
Open ASR
Acoustic model.
Open-source transcription baseline.
- Open-weight acoustic models (multilingual)
- Pre-trained on web-scale audio
- Word tokens with timestamps
- Permissive licensing (MIT, Apache 2.0)
- CPU, GPU, and NPU inference
- Quantized variants for mobile
- On-device ASR builds
- ASR baseline of record
EdgeLance Audio
Voice intelligence.
Doctrine-grade comprehension.
- Source-profile VAD (radio, body-worn, camera, clean)
- Voice fingerprint speaker ID against enrolled bank
- Doctrine normalizer (brevity, callsigns, hallucination filter)
- Citation anchor: every token bound to source-media timestamp
- Continuous surveillance with threat-phrase triggers
- Voiceprint threat watch list with severity routing
- Doctrine compliance scoring with reviewer feedback loop
- Closed-loop adapter: squad-bound LoRA under burn lifecycle
See it on your mission.
We run the capability on your mission thread, on hardware your team already has.
Request a briefing