Video
Open models detect. EdgeLance remembers.
Open-source detection covers the frame. EdgeLance adds the zones, the people, the plates, the evidence chain, and the fleet.
In the product
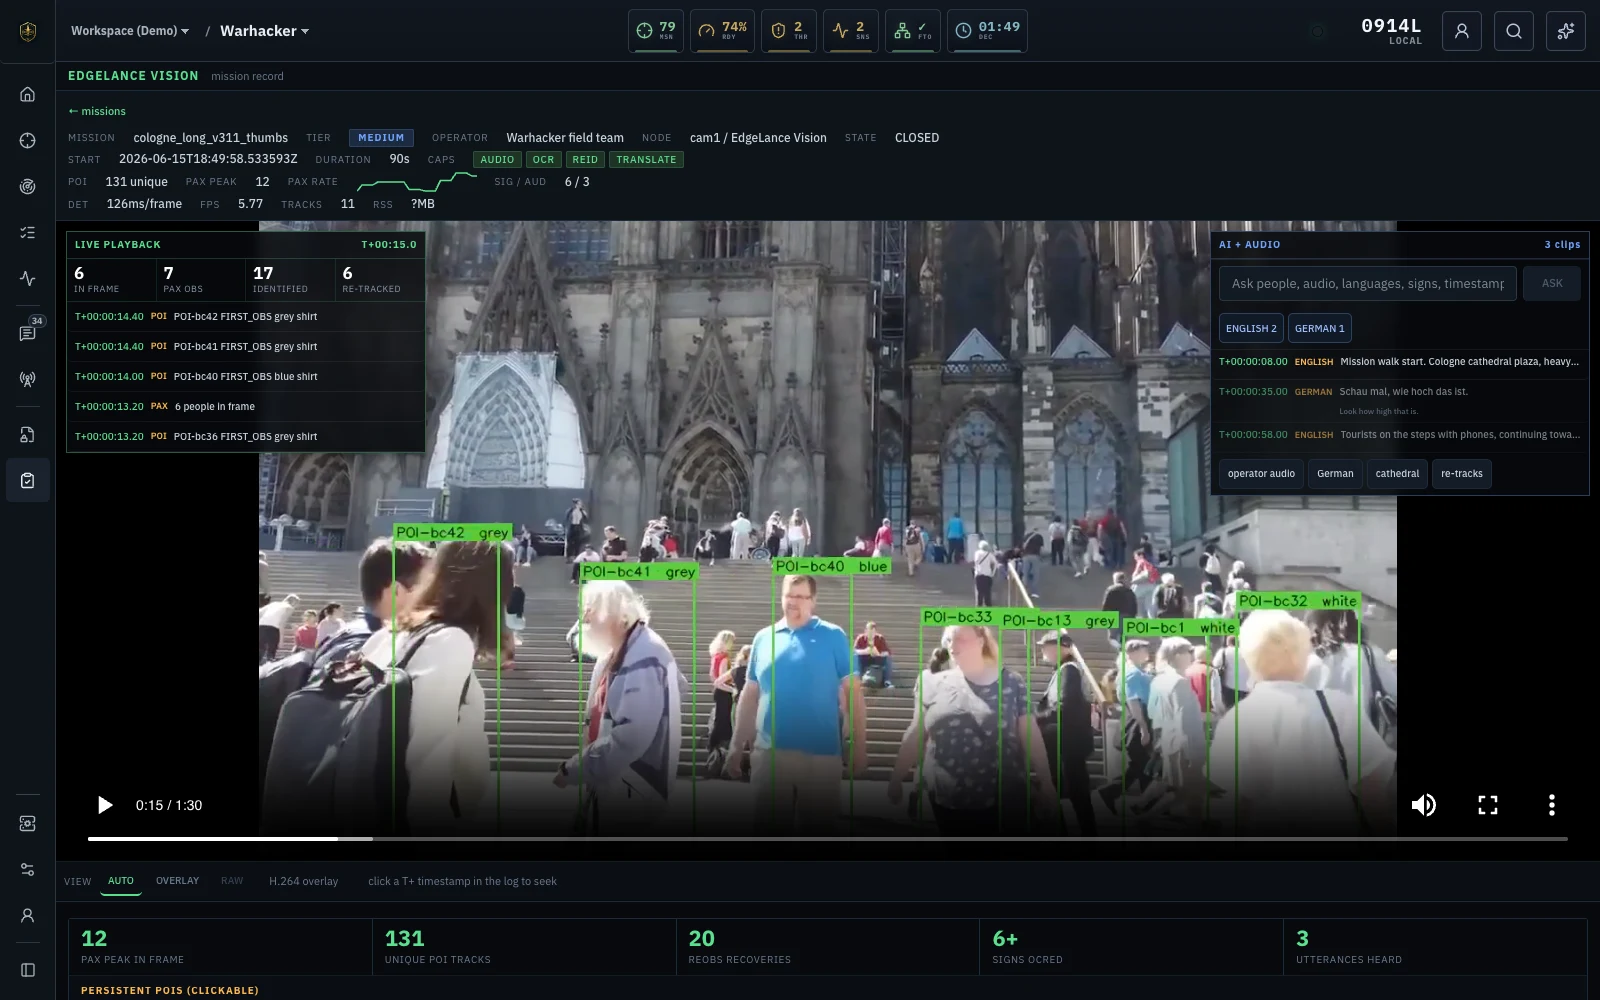
The frame becomes a searchable mission record.
Recorded or live video becomes person detection, persistent track IDs, re-identification, OCR, multilingual audio, and time-linked events, processed on local hardware inside the EdgeLance Vision workspace.
Open CV
Detection backbone.
Open-source frame inference.
- Open-weight detection backbones
- Open-weight segmentation models
- Open-weight recognition models
- Pre-trained on web-scale image data
- Permissive licensing
- CPU, GPU, and NPU inference
- Quantized variants for mobile
- Frame-by-frame inference baseline
EdgeLance Video
Vision intelligence.
Camera fleet, evidence, and recall.
- Camera optimization (motion cadence, latency stepdown, thermal pressure)
- Zone alerts and camera tasking
- Face matching and re-identification
- License plate recognition
- Body cam, vehicle cam, drone payload streams
- Scene understanding and OCR
- Camera fleet registry and health
- Evidence binding: photo and video proof on tasks, markers, and AAR
See it on your mission.
We run the capability on your mission thread, on hardware your team already has.
Request a briefing